Introducing DolphinX, an Enterprise-Grade Platform for Agent Development and Governance

Introducing DolphinX, an Enterprise-Grade Platform for Agent Development and Governance

This post explores the core building blocks of DolphinDB's distributed computing framework: data sources, the MapReduce model, and iterative computing — along with the architectural concept of compute-storage separation that underpins the whole system.

This article explains how DolphinDB replays historical data into streaming pipelines, and how it enables accurate simulation of real-time trading environments for strategy research, testing, and validation.

In this article, we explore DolphinDB’s streaming framework through practical, real-world examples—from stateless calculations to stateful windowed aggregations—and explain how it unifies stream and batch processing in a single system.

By leveraging LLVM, DolphinDB enables high-performance numerical computing, advanced financial modeling, and iterative algorithms to be written in concise, expressive Dlang.

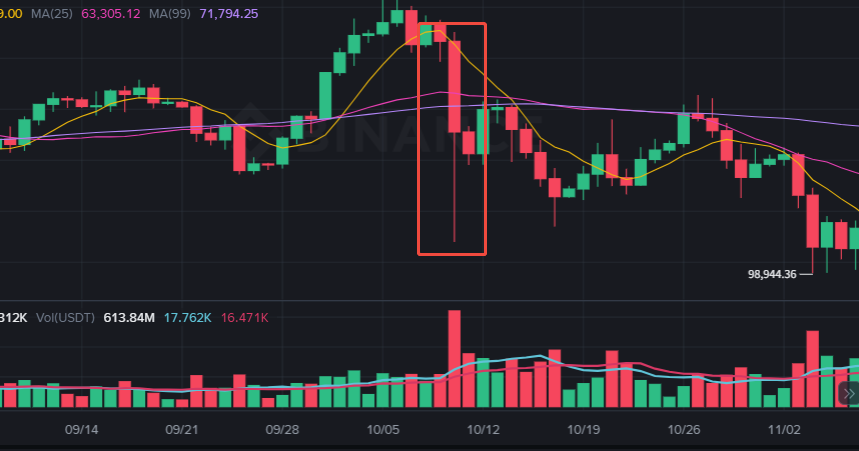
Can crypto flash wicks be predicted before they happen? Using the October 2025 $19B liquidation event as a case study, this article shows how VPIN, order book imbalance, and market microstructure can uncover early warning signals before extreme price movements occur.

DolphinDB’s high-performance market data replay and Order Matching Simulator Plugin provides a low-latency, high-throughput solution for strategy validation. By integrating the plugin directly into an existing C++ backtesting framework, institutions can reuse their current infrastructure while taking advantage of DolphinDB’s ultra-fast computing capabilities, making it an ideal solution for high-frequency strategy simulation.

This post walks through a complete, production-oriented solution using DolphinDB together with the INSIGHT market data plugin to generate 1-second order book snapshots across all SSE and SZSE stocks and funds in real time. We'll cover everything from plugin installation to post-market batch writes to a distributed database — with the actual scripts you'd run in production.

DolphinDB unifies heterogeneous industrial data (OPC UA, MQTT, Kafka) into one pipeline, with partitioned storage, stream-batch unified computation, and standard APIs. It replaces the slow relational DB underneath MES, cutting query times dramatically without replacing MES itself.

In this post, we explore DolphinDB’s streaming engine architecture and walk through practical examples.