By leveraging LLVM, DolphinDB enables high-performance numerical computing, advanced financial modeling, and iterative algorithms to be written in concise, expressive Dlang.

By leveraging LLVM, DolphinDB enables high-performance numerical computing, advanced financial modeling, and iterative algorithms to be written in concise, expressive Dlang.

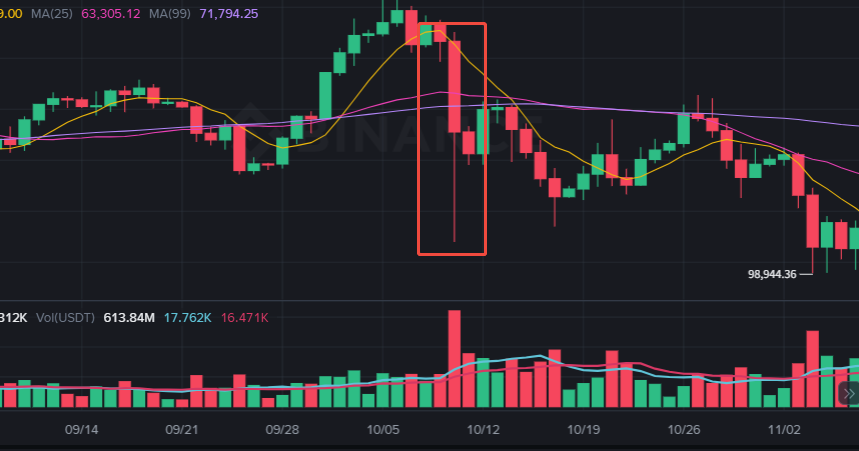
Can crypto flash wicks be predicted before they happen? Using the October 2025 $19B liquidation event as a case study, this article shows how VPIN, order book imbalance, and market microstructure can uncover early warning signals before extreme price movements occur.

DolphinDB’s high-performance market data replay and Order Matching Simulator Plugin provides a low-latency, high-throughput solution for strategy validation. By integrating the plugin directly into an existing C++ backtesting framework, institutions can reuse their current infrastructure while taking advantage of DolphinDB’s ultra-fast computing capabilities, making it an ideal solution for high-frequency strategy simulation.

This post walks through a complete, production-oriented solution using DolphinDB together with the INSIGHT market data plugin to generate 1-second order book snapshots across all SSE and SZSE stocks and funds in real time. We'll cover everything from plugin installation to post-market batch writes to a distributed database — with the actual scripts you'd run in production.

DolphinDB unifies heterogeneous industrial data (OPC UA, MQTT, Kafka) into one pipeline, with partitioned storage, stream-batch unified computation, and standard APIs. It replaces the slow relational DB underneath MES, cutting query times dramatically without replacing MES itself.

In this post, we explore DolphinDB’s streaming engine architecture and walk through practical examples.

This article walks through the complete ML workflow in DolphinDB: from data ingestion and preprocessing to model training, evaluation, and deployment. We'll explore supervised and unsupervised learning, demonstrate distributed training at scale, and conclude with a production financial case study.

This article shows how DolphinDB's AI DataLoader eliminates the data pipeline bottleneck. We'll build a production-ready stock price prediction model, demonstrating how to seamlessly connect database-scale factor data with PyTorch—without the usual memory management headaches.

This article walks through exactly that transformation, using DolphinDB as the computing layer. We’ll cover both the batch path (historical data, processed in parallel) and the streaming path (real-time data, processed with sub-millisecond latency), with the same core logic running in both.

Using simulated tick-by-tick trade data from the Shanghai Stock Exchange on a single trading day in 2020, we’ll calculate minute-level capital flow — splitting buy and sell orders into “large” and “small” buckets based on a 50,000-share threshold — and stream the results live into a dashboard.